Technical Introduction to Recommendation Service

As described in the product overview of the Recommendation Service, PEACH provides a complete workflow to conveniently implement the data collection, exploration, processing, distribution, evaluation and monitoring necessary to deliver recommendations for each user.
Data Collection
PEACH provides several client libraries (iOS / Android / web)for the collection of user events. They are implemented in a very similar way than you would know from Google Analytics or any other common website analytics tool.
The events are sent to an acquisition REST API which collects all events one by one or by batch and sends them through the pipeline to be stored on storage.
- client libraries are integrated in the clients and will send events that the user triggered by its consumption (playing media, visiting a page, reading an article,...)
- Data collection REST endpoints are hosted on a Python AIOHTTP web server.
- For scaling and fault tolerance reasons the data is then pushed to Apache Kafka
- The data is picked up from the data topics by Kafka Connect and persisted onto S3
- Data is stored in JSON format in S3 buckets
Recommendation algorithms
The second step in the recommendation process is described and integrated in the Data Science workflow section. Algorithms are written in Jupyter Notebooks, and deployed as Tasks to create the model, and as REST API endpoints to infer recommendation for clients. Most of the operations and actions are handled within the PEACH Lab, by the use of configuration files, allowing the broadcaster to control the evaluation and distribution endpoints.
See the Introduction to Data Scientist Platform .
Processing & Distribution
The algorithms developed by the data scientists are converted into Tasks that process the collected data in order to provide updated models for the recommendations.
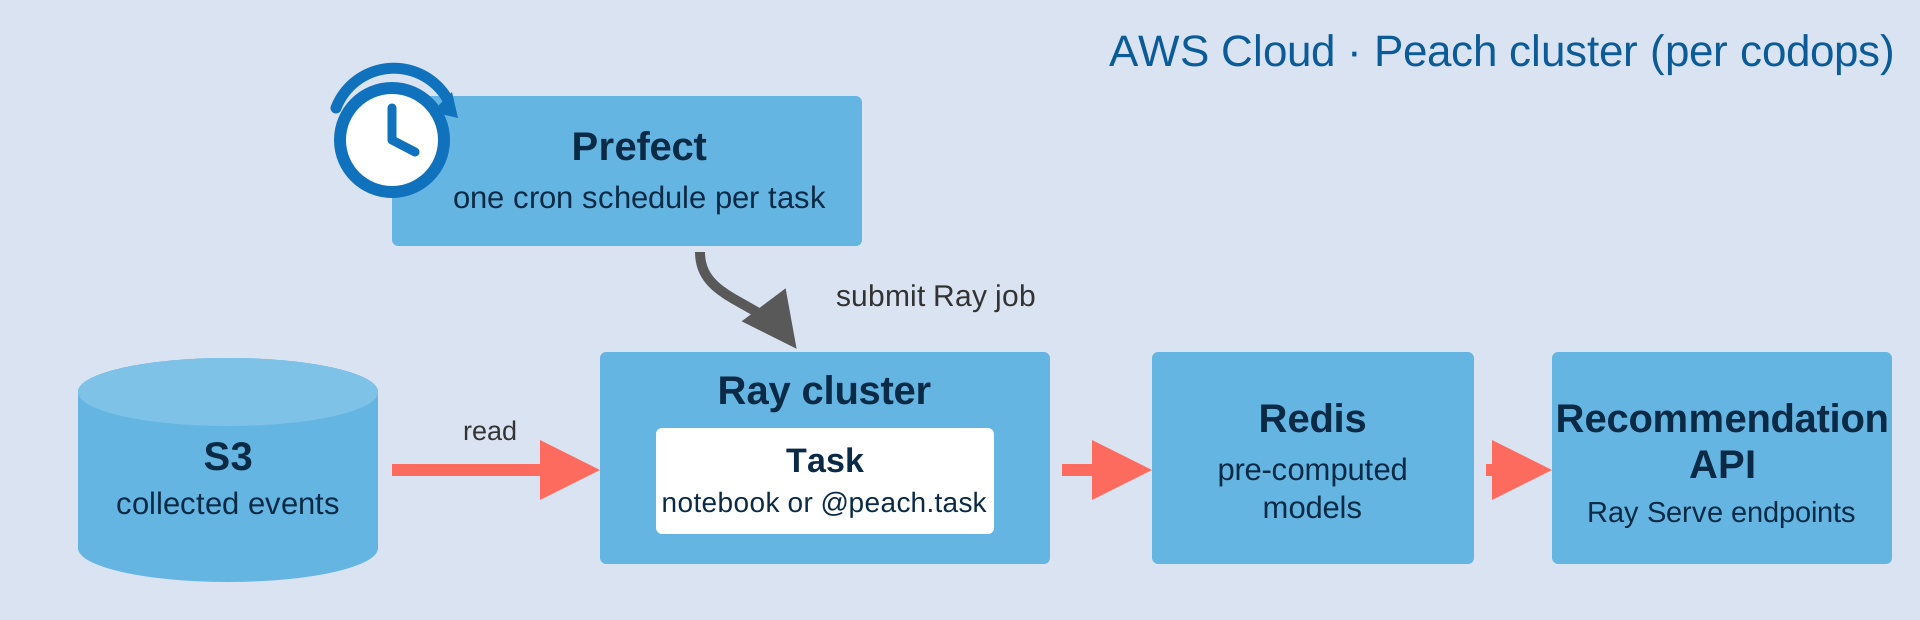
Each task is scheduled on its own. There is no single scheduler walking through the tasks one after another: Prefect holds one deployment per task, each with its own cron schedule, so tasks run on their own cadence and independently of each other.
- Every task gets a Prefect deployment with a cron schedule of its own. Set it with
cron:in yourpeach.conf(orcron=on a@peach.task). Without one, the task falls back to a schedule derived fromminimal_delay, which defaults to every 6 hours, at a minute derived from the task name so that tasks do not all fire at once. - When a schedule fires, Prefect starts a flow run in its own Kubernetes pod, which submits the task to the codops' Ray cluster as a Ray job.
- The task reads the collected data from S3 and runs on the Ray cluster with the CPU, GPU and memory it asked for.
- The pre-computed recommendation models are stored inside Redis to allow faster access by the Recommendation API. Vector embeddings are pushed to Milvus instead, for similarity search.
- The Recommendation API computes the Recommendation List for a particular user from the data stored in Redis
Each run — its state, duration, logs and history — is visible in Prefect at https://prefect.{codops}.peach.ebu.io/. A schedule can also be switched off there, and that outranks the configuration: a task descheduled in the Prefect UI stays descheduled across deploys.
Distribution : Recommendation API
Once the models are computed they are made available through the Recommendation API. The endpoints provide a way to query and execute the computation necessary to build the list of recommendations given user id, content id, or other parameters. This typically involves using a model stored in Redis, and further post processing to apply business rules.
The way how the Recommendation API is queried depends on the integration: in most cases, the broadcasters backend will query the Recommendation API and build a more elaborate list with metadata to be returned to a visitor. In some cases querying the Recommendation API is directly made from the clients. Additionally a list of content can be placed on a CDN to work as a fallback in case the Recommendation API experiences issues and does not return in proper time.
See also : Recommendation API
Evaluation and Monitoring
Human inspection
Using Spectrum, Data Scientist as well as Product Owners can evaluate the relevance of the algorithm, detect special cases that need additional refinements before the roll out the recommendation to production.
AB Testing
Measuring and improving algorithm requires an A/B or Testing environment. The Recommendation API offer this, and dashboards show the performance of the alternatives.
The evaluation of the recommendation follows the workflow below. Based on the configuration of the experiment, a model is selected to a request based on the user's id, its cookies or randomly. This allows a consistent research and testing framework for data scientists. Additionally if the model computation does not return a consistent list another fallback list can be chosen to overcome cold start issues.
See also : Recommendation API
